PanoSeg3R

Feed-Forward 3D Semantic Segmentation for Panoramic Images with an Automatic Data Curation Pipeline

University of Maryland, College Park

Overview

Panoramas in, a labeled 3D scene out

We present PanoSeg3R, a feed-forward framework for 3D panoramic semantic segmentation.

  • Feed-forward 3D semantic segmentation from multiple panoramas, with no per-scene optimization.
  • An automatic panorama data curation pipeline that combines off-the-shelf foundation models to generate reliable pseudo semantic labels, expanding the training data and improving zero-shot generalization.
  • State-of-the-art panoramic 3D semantic segmentation, improving 3D mIoU by up to 16.02 on ScanNet++.
  • With curated data, zero-shot mIoU further improves by 4.26 and 43.28 on Stanford2D3D and ToF-360, respectively, compared to training without curated data.
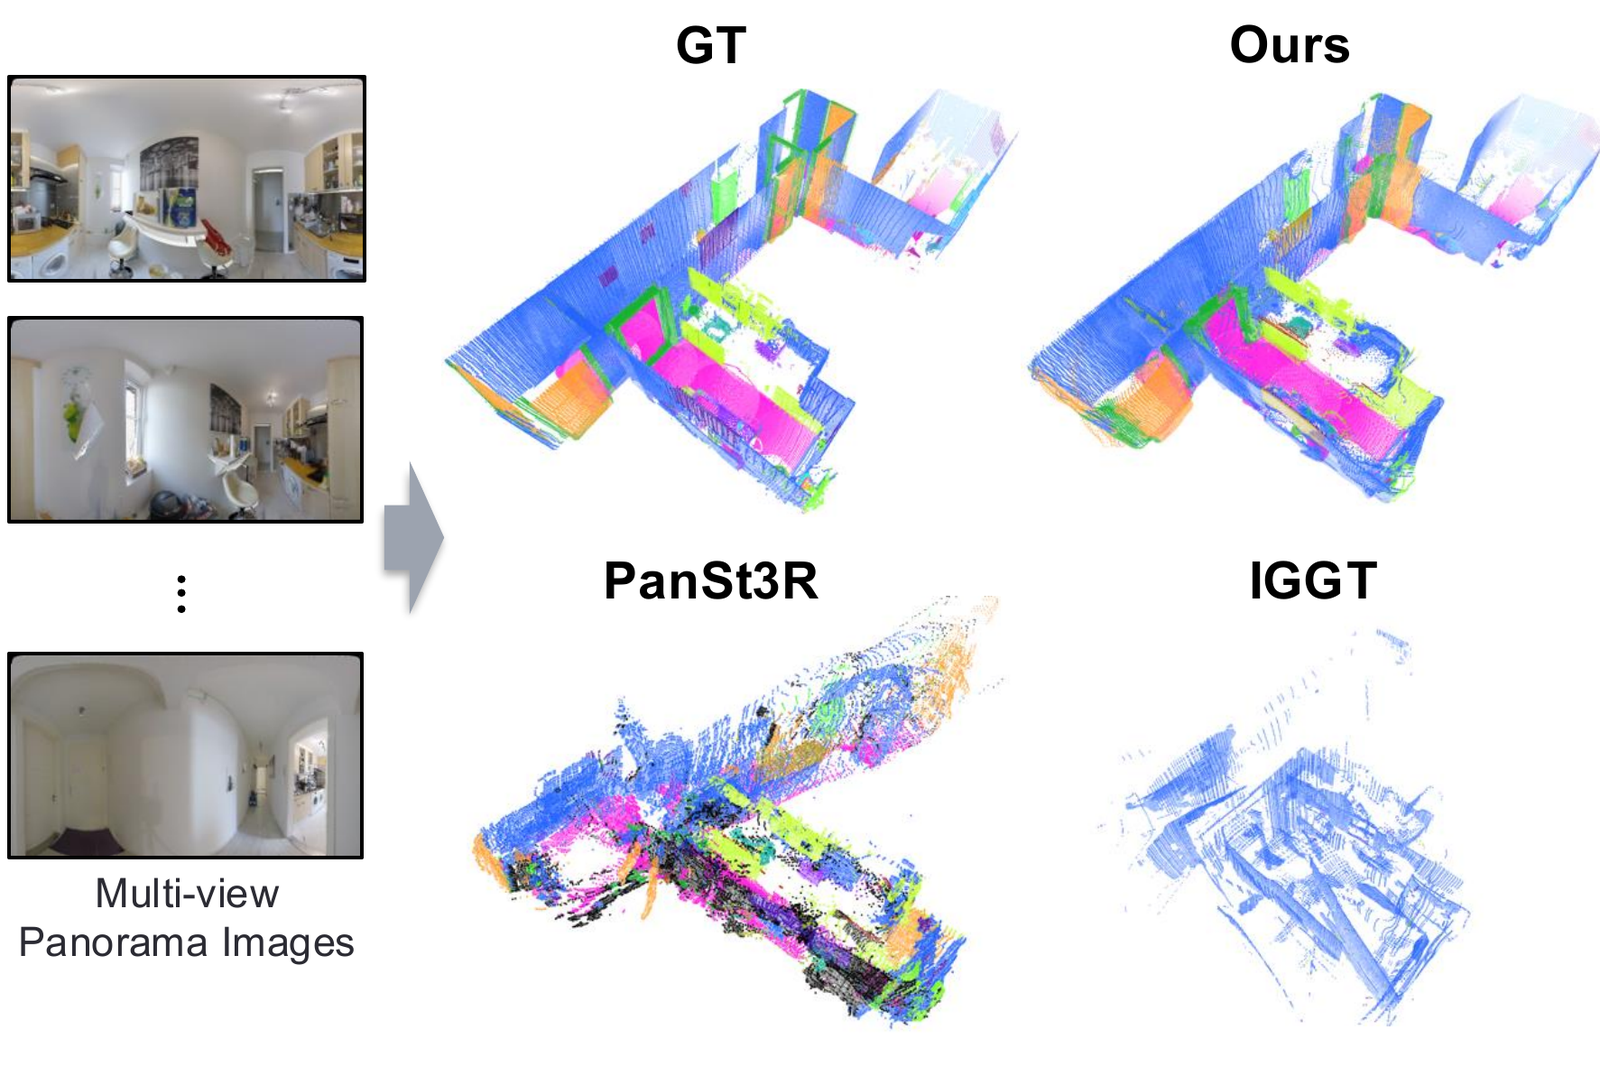
Multi-view panoramas in, 3D semantic point clouds out: ground truth, ours, PanSt3R and IGGT.
From the same multi-view panoramas, PanSt3R and IGGT lose geometry and labels. Ours stays close to GT.

Method

Architecture

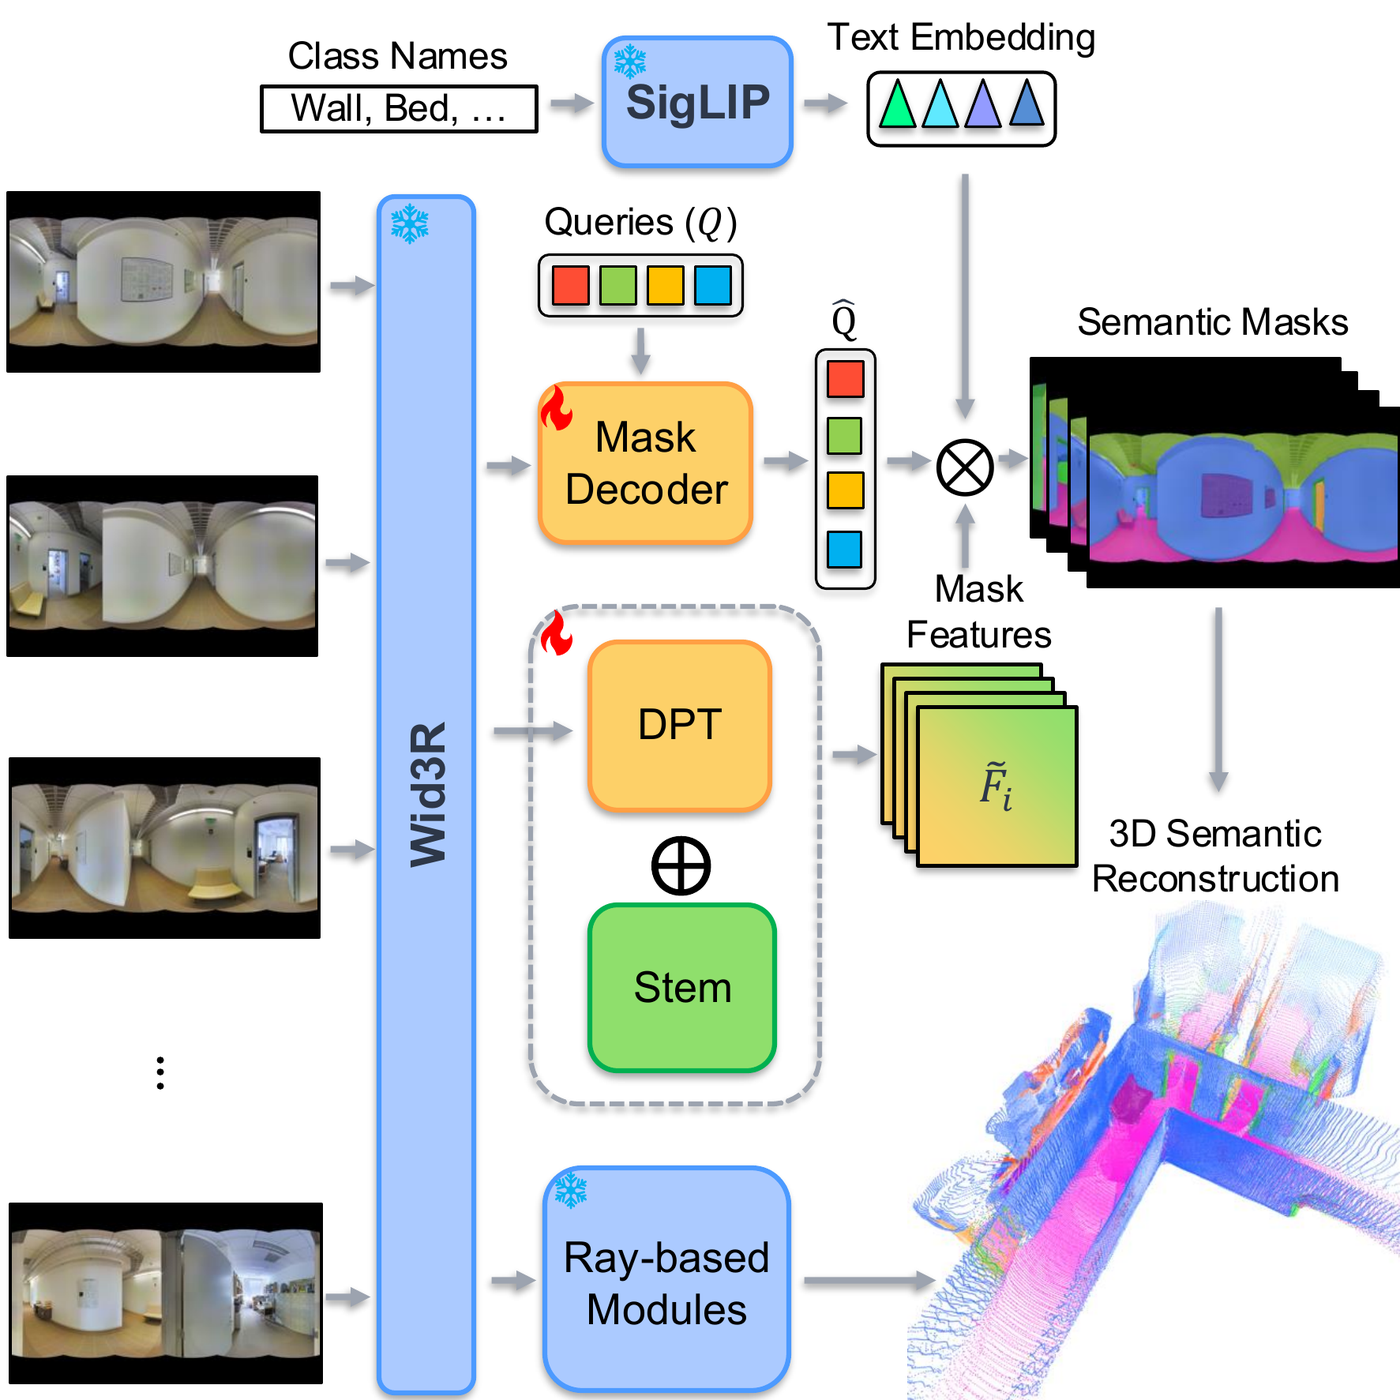
Architecture: frozen Wid3R backbone, mask decoder with learnable queries, DPT plus image stem for mask features, SigLIP text embeddings, ray-based modules for 3D.

Multi-view equirectangular projection (ERP) images are processed by the pretrained Wid3R backbone to extract features.

These features are refined by a query-based decoder, while a DPT head produces dense feature maps. An image stem injects low-level features into the feature maps to complement the decoded representations.

We reconstruct 3D geometry through the ray-based modules and project the predicted semantic masks to obtain consistent 3D semantic segmentation.

Data

Automatic data curation

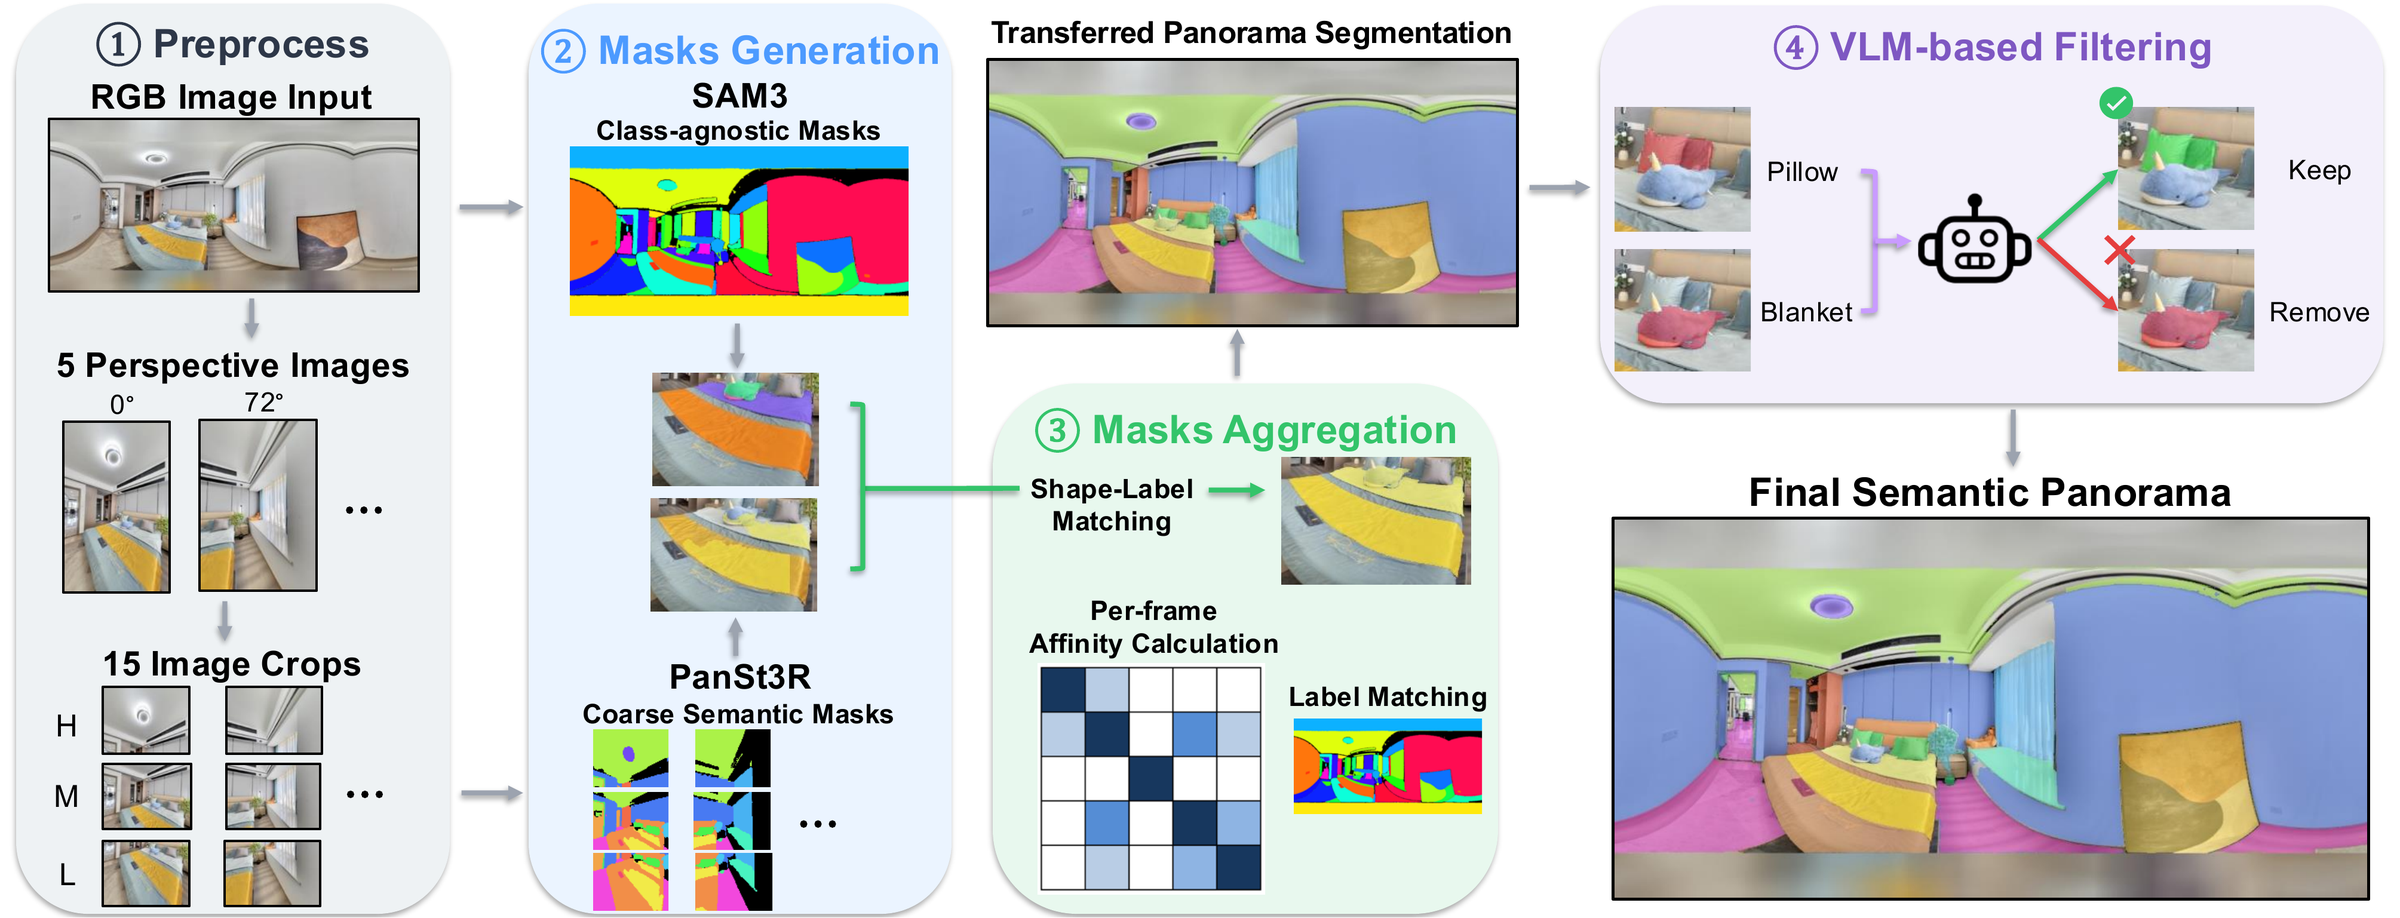
Real panorama datasets rarely come with semantic labels. The pipeline labels unannotated Realsee3D and OmniScenes panoramas automatically.

Curation pipeline: preprocess, mask generation, mask aggregation, VLM-based filtering.
  1. Preprocess

    Each panorama is split into 5 perspective images and 15 crops.

  2. Mask generation

    SAM3 gives class-agnostic masks. PanSt3R gives coarse semantic masks.

  3. Mask aggregation

    IoU matches SAM3 masks with PanSt3R regions and gives each mask the corresponding label.

  4. VLM filtering

    A VLM keeps or removes each labeled mask, giving the final semantic panorama.

Curated Panorama Segmentation Data

Pick a panorama. Hover over either image or a class to see where each label lands.

Panorama Selected RGB panorama
Curated semantic label

Interactive

Explore the 3D results

Pick a scene. The left viewer shows PanoSeg3R, the right one GT or a baseline. Both cameras move together.

Input panoramas
PanoSeg3R (ours)
drag: rotate · right-drag: pan · scroll: zoom
Classes in view hover or click a class to highlight it

    Point clouds are randomly downsampled to at most 150k points for the browser. All predictions are shown in the GT frame.

    Cite

    BibTeX

    @article{yoon2026panoseg3r,
      title   = {PanoSeg3R: Feed-Forward 3D Semantic Segmentation for Panoramic Images
                 with an Automatic Data Curation Pipeline},
      author  = {Yoon, Heechan and Jung, Dongki and Nguyen, Phuc and Lin, Ming and Manocha, Dinesh},
      journal = {arXiv preprint},
      year    = {2026}
    }